Jialong Xue
I am a first-year master's student at Shanghai Jiao Tong University, where I earned my bachelor's degree in Information Engineering. I am advised by Prof. Guo Lu.
My research focuses on omni-modal models, with an emphasis on integrating vision, audio, and language for natural, real-time interaction.
During my research internship at StepFun, I worked on audio-language model post-training and contributed to full-duplex dialogue for StepAudio 3 Realtime and StepLive.
Warning
Problem: The current name of your GitHub Pages repository ("Solution: Please consider renaming the repository to "
http://".
However, if the current repository name is intended, you can ignore this message by removing "{% include widgets/debug_repo_name.html %}" in index.html.
Action required
Problem: The current root path of this site is "baseurl ("_config.yml.
Solution: Please set the
baseurl in _config.yml to "News
Selected Publications (view all )
StepAudio 3 Realtime Technical Report
Bin Lin, Bo Zhao, Boyang Zhang, …, Jialong Xue, …
arXiv preprint arXiv:2609.14005 2026
StepAudio 3 Realtime integrates audio understanding, full-duplex conversation, parallel reasoning and speech generation, and voice-based task execution. It supports natural turn-taking and interruptions, with asynchronous tool use that keeps conversations flowing. My contributions: primarily full-duplex interaction and Voice Agent capabilities.
StepAudio 3 Realtime Technical Report
Bin Lin, Bo Zhao, Boyang Zhang, …, Jialong Xue, …
arXiv preprint arXiv:2609.14005 2026
StepAudio 3 Realtime integrates audio understanding, full-duplex conversation, parallel reasoning and speech generation, and voice-based task execution. It supports natural turn-taking and interruptions, with asynchronous tool use that keeps conversations flowing. My contributions: primarily full-duplex interaction and Voice Agent capabilities.
Unified Spatiotemporal Token Compression for Video-LLMs at Ultra-Low Retention
Junhao Du*, Jialong Xue*, Anqi Li, Jincheng Dai, Guo Lu
IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) 2026
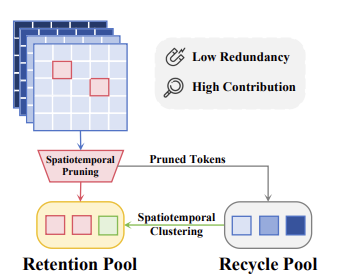
We formulate token compression for Video-LLMs as a unified spatiotemporal allocation problem under a global retention budget. The method preserves strong video understanding performance at ultra-low token retention without retraining.
Unified Spatiotemporal Token Compression for Video-LLMs at Ultra-Low Retention
Junhao Du*, Jialong Xue*, Anqi Li, Jincheng Dai, Guo Lu
IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) 2026
We formulate token compression for Video-LLMs as a unified spatiotemporal allocation problem under a global retention budget. The method preserves strong video understanding performance at ultra-low token retention without retraining.
All publications
Education

Experience

